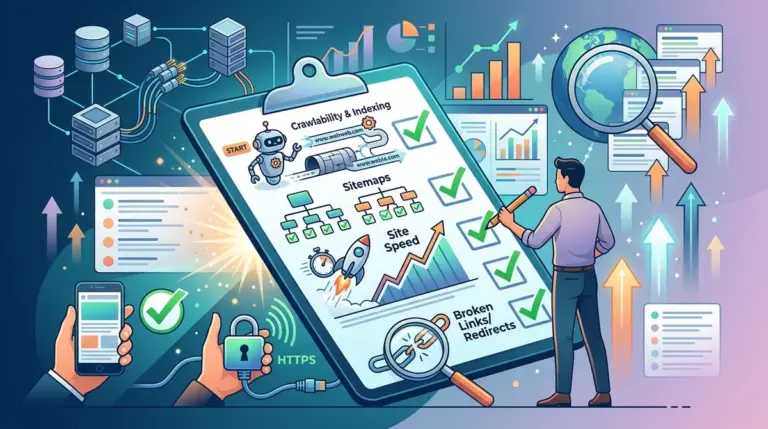
Indexability is the gatekeeper of organic search visibility. If a page cannot be added to a search engine's database, no amount of keyword optimization or backlink building will generate traffic. While crawlability refers to a search engine's ability to access a page, indexability is the engine's decision to store and display that page in search results. For SEO professionals, managing this distinction is the difference between a functional site and a ghost town of unranked URLs. Understanding the exact difference between crawlability versus indexability is key to unlocking a site's full search potential.
Distinguishing Crawlability from Indexability
It is a common mistake to use these terms interchangeably. Crawlability is the technical accessibility of your site. If your robots.txt file blocks a folder, or if your server returns a 5xx error, the crawler (like Googlebot) cannot reach the content. Indexability comes after the crawl. It is the status of a page that has been successfully analyzed and deemed worthy of the search index.
Key Distinction: A page can be perfectly crawlable but not indexable. For example, a page that contains a "noindex" tag is easily crawled, but the crawler is explicitly told not to add it to the search database. Conversely, a page that is not crawlable can never become indexable because the search engine never sees the content in the first place.
The Technical Requirements for Indexation
For a page to be indexed, it must meet several technical criteria. If any of these are misconfigured, the page will remain invisible to users regardless of its content quality.
Robots Directives and Meta Tags
The primary way to control indexability is through the <meta name="robots" content="noindex"> tag or the X-Robots-Tag in the HTTP header. These directives are the most common cause of "missing" pages in search results. Developers often use "noindex" on staging environments to prevent duplicate content issues, but these tags frequently migrate to the live production site by mistake.
- noindex: Tells search engines not to show the page in search results.
- nofollow: Tells search engines not to follow the links on that page.
- none: Equivalent to using both noindex and nofollow.
- noimageindex: Specifically prevents images on the page from being indexed.
Canonical Tags and URL Parameters
The rel="canonical" tag is a suggestion to search engines about which version of a URL is the "master" copy. If you have multiple URLs with similar content—such as product pages with different sorting parameters—the canonical tag tells Google to index only the primary version. If a canonical tag points to a different URL, the current page will likely not be indexed. This is not an "error," but a deliberate choice to consolidate ranking signals.
Warning: Improperly implemented self-referencing canonicals on paginated series (like blog archives) can lead to "Discovery" issues where Google stops crawling deeper pages because it perceives them as duplicates of the first page.
Server-Side Obstacles to Indexing
The communication between your web server and the search engine bot determines whether a page is eligible for the index. Search engines prioritize "healthy" pages that return a 200 OK status code.
Best for Technical Audits: Regularly monitoring your server logs to see how often Googlebot encounters 4xx or 5xx errors. A high frequency of 404 (Not Found) or 410 (Gone) errors tells the indexer that your site is unreliable, leading to the eventual removal of those URLs from the index. Similarly, "Soft 404s"—where a page tells the user it doesn't exist but tells the server it is "200 OK"—can confuse indexers and waste crawl budget on empty pages.
Content Quality as an Indexing Filter
In recent years, Google has moved away from indexing everything it finds. Indexing is now a resource-heavy process, and search engines use quality filters to decide if a page deserves "shelf space."
Thin content, auto-generated text, and pages with high "boilerplate" ratios (where the header, footer, and sidebar contain more text than the unique body content) are often excluded from the index. This status is usually reported in Google Search Console as "Crawled - currently not indexed." This means the technical path was clear, but the content did not meet the threshold for inclusion.
How to Monitor Indexing Health
To ensure your site is properly indexed, you must move beyond manual checks and use diagnostic tools that reflect the search engine's perspective.
Google Search Console (GSC): The Index Coverage report is the definitive source of truth. It categorizes URLs into "Valid," "Excluded," or "Error." Pay close attention to the "Excluded" section to identify if pages are missing due to "noindex" tags, canonical mismatches, or quality issues.
Site: Search: Performing a site:SEO Learning Center search in Google provides a rough estimate of how many pages are indexed. However, this is an approximation and should not be used for precise technical reporting.
URL Inspection Tool: This allows you to test a specific URL in real-time to see if Google can see it, if it's eligible for indexing, and if any mobile usability issues are preventing its inclusion.
Immediate Steps to Resolve Indexing Errors
If you discover that critical revenue-generating pages are missing from the search results, follow this sequence to restore them:
- Check for "noindex" tags: View the page source (Ctrl+U) and search for the word "noindex." If it exists, remove it.
- Verify Robots.txt: Ensure the URL is not being blocked by a "Disallow" rule. Even if a page is not blocked, a "noindex" tag inside a blocked folder cannot be seen, which sometimes leads to the page staying in the index longer than intended but without a description.
- Check the Canonical: Ensure the
rel="canonical"points to the URL itself, not a different page or a defunct version of the site (like an old HTTP or non-www URL). - Request Indexing: Once the technical fix is live, use the "Request Indexing" feature in Google Search Console to move the URL to the front of the crawl queue.
- Improve Content Depth: If the page is "Crawled - currently not indexed," add unique value, internal links, and expert-level detail to signal to the engine that the page is useful for searchers.
Frequently Asked Questions
How long does it take for Google to index a new page?
Indexation can take anywhere from a few hours to several weeks. Factors like site authority, internal linking, and the presence of the URL in an XML sitemap influence the speed. For new sites with low authority, the process is generally slower.
Does an XML sitemap guarantee indexation?
No. A sitemap is a "discovery" tool, not an "indexing" tool. It tells Google that the pages exist and where to find them, but Google still evaluates each page for quality and technical directives before deciding to index it.
Can I force Google to remove a page from the index?
Yes. The fastest way is to add a "noindex" tag to the page. Alternatively, you can use the Removals Tool in Google Search Console for a temporary (6-month) block, which is useful for sensitive information that was accidentally published.
Why is my homepage indexed but my subpages aren't?
This usually indicates a "crawl depth" issue. If your subpages are not linked internally from the homepage or main navigation, search engines may not find them. It could also suggest that your subpages are seen as duplicate or low-quality content compared to the homepage.